Five Days of Microsoft AI Models - Day 3
Listen, Speak, See
Exploring Microsoft's transcription, voice, and image models as specialized building blocks, with practical use cases and preview limitations.
Reasoning and coding get the headlines. But if you count where Microsoft AI has shipped the most, it's somewhere else: the models that turn sound into text, text into sound, and words into pictures. This is where MAI started, and where it moves fastest.
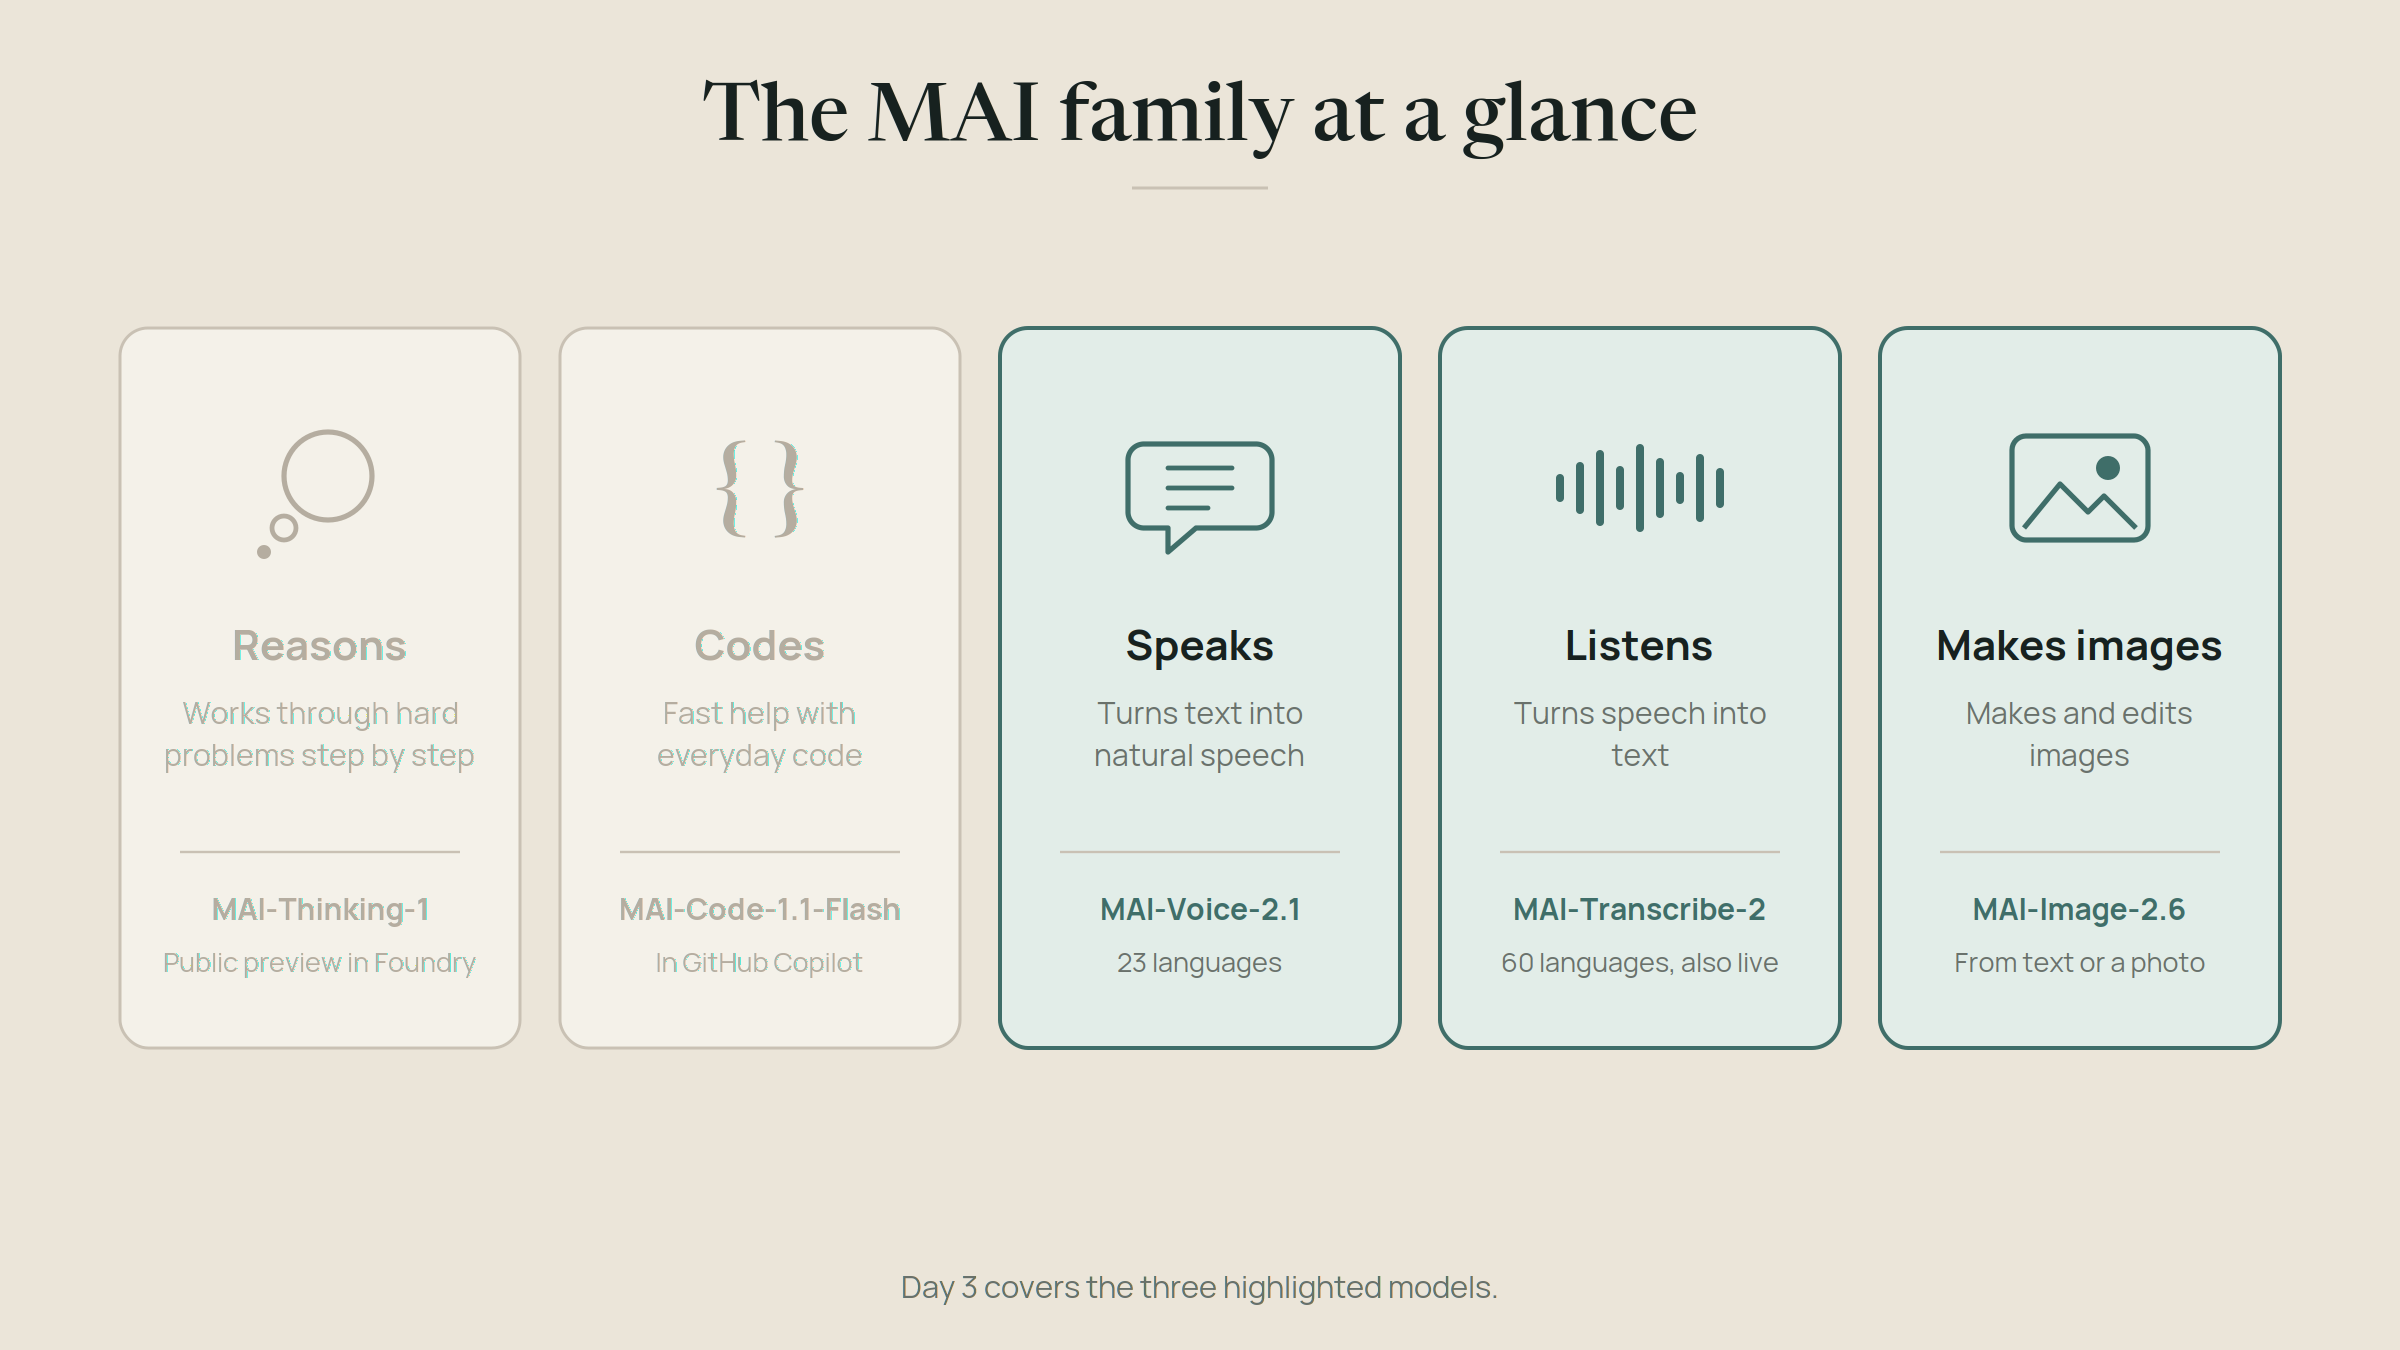
Listen: MAI-Transcribe-2 and the streaming version
Speech recognition, also called ASR (automatic speech recognition), turns audio into text. Microsoft now has two versions, for two different jobs.
MAI-Transcribe-2 is for recordings: meetings, podcasts, interviews, call archives. It was released on September 3. It covers 60 languages, up from 43 in the previous version, and adds speaker diarization (knowing who said what), word-level timestamps, and the ability to follow a conversation that switches between languages. Microsoft offers it at an introductory $0.10 per hour of audio until the end of the year.
Microsoft's headline calls it the fastest, most accurate and cheapest speech recognition model in the world. The independent picture is good but more nuanced. On Artificial Analysis, it measures among the most accurate models, with a word error rate of 2.0%, meaning about two wrong words per hundred. But it's not the fastest on that board: Deepgram's Nova-3 has a higher speed factor. Strong, but not the fastest everywhere.
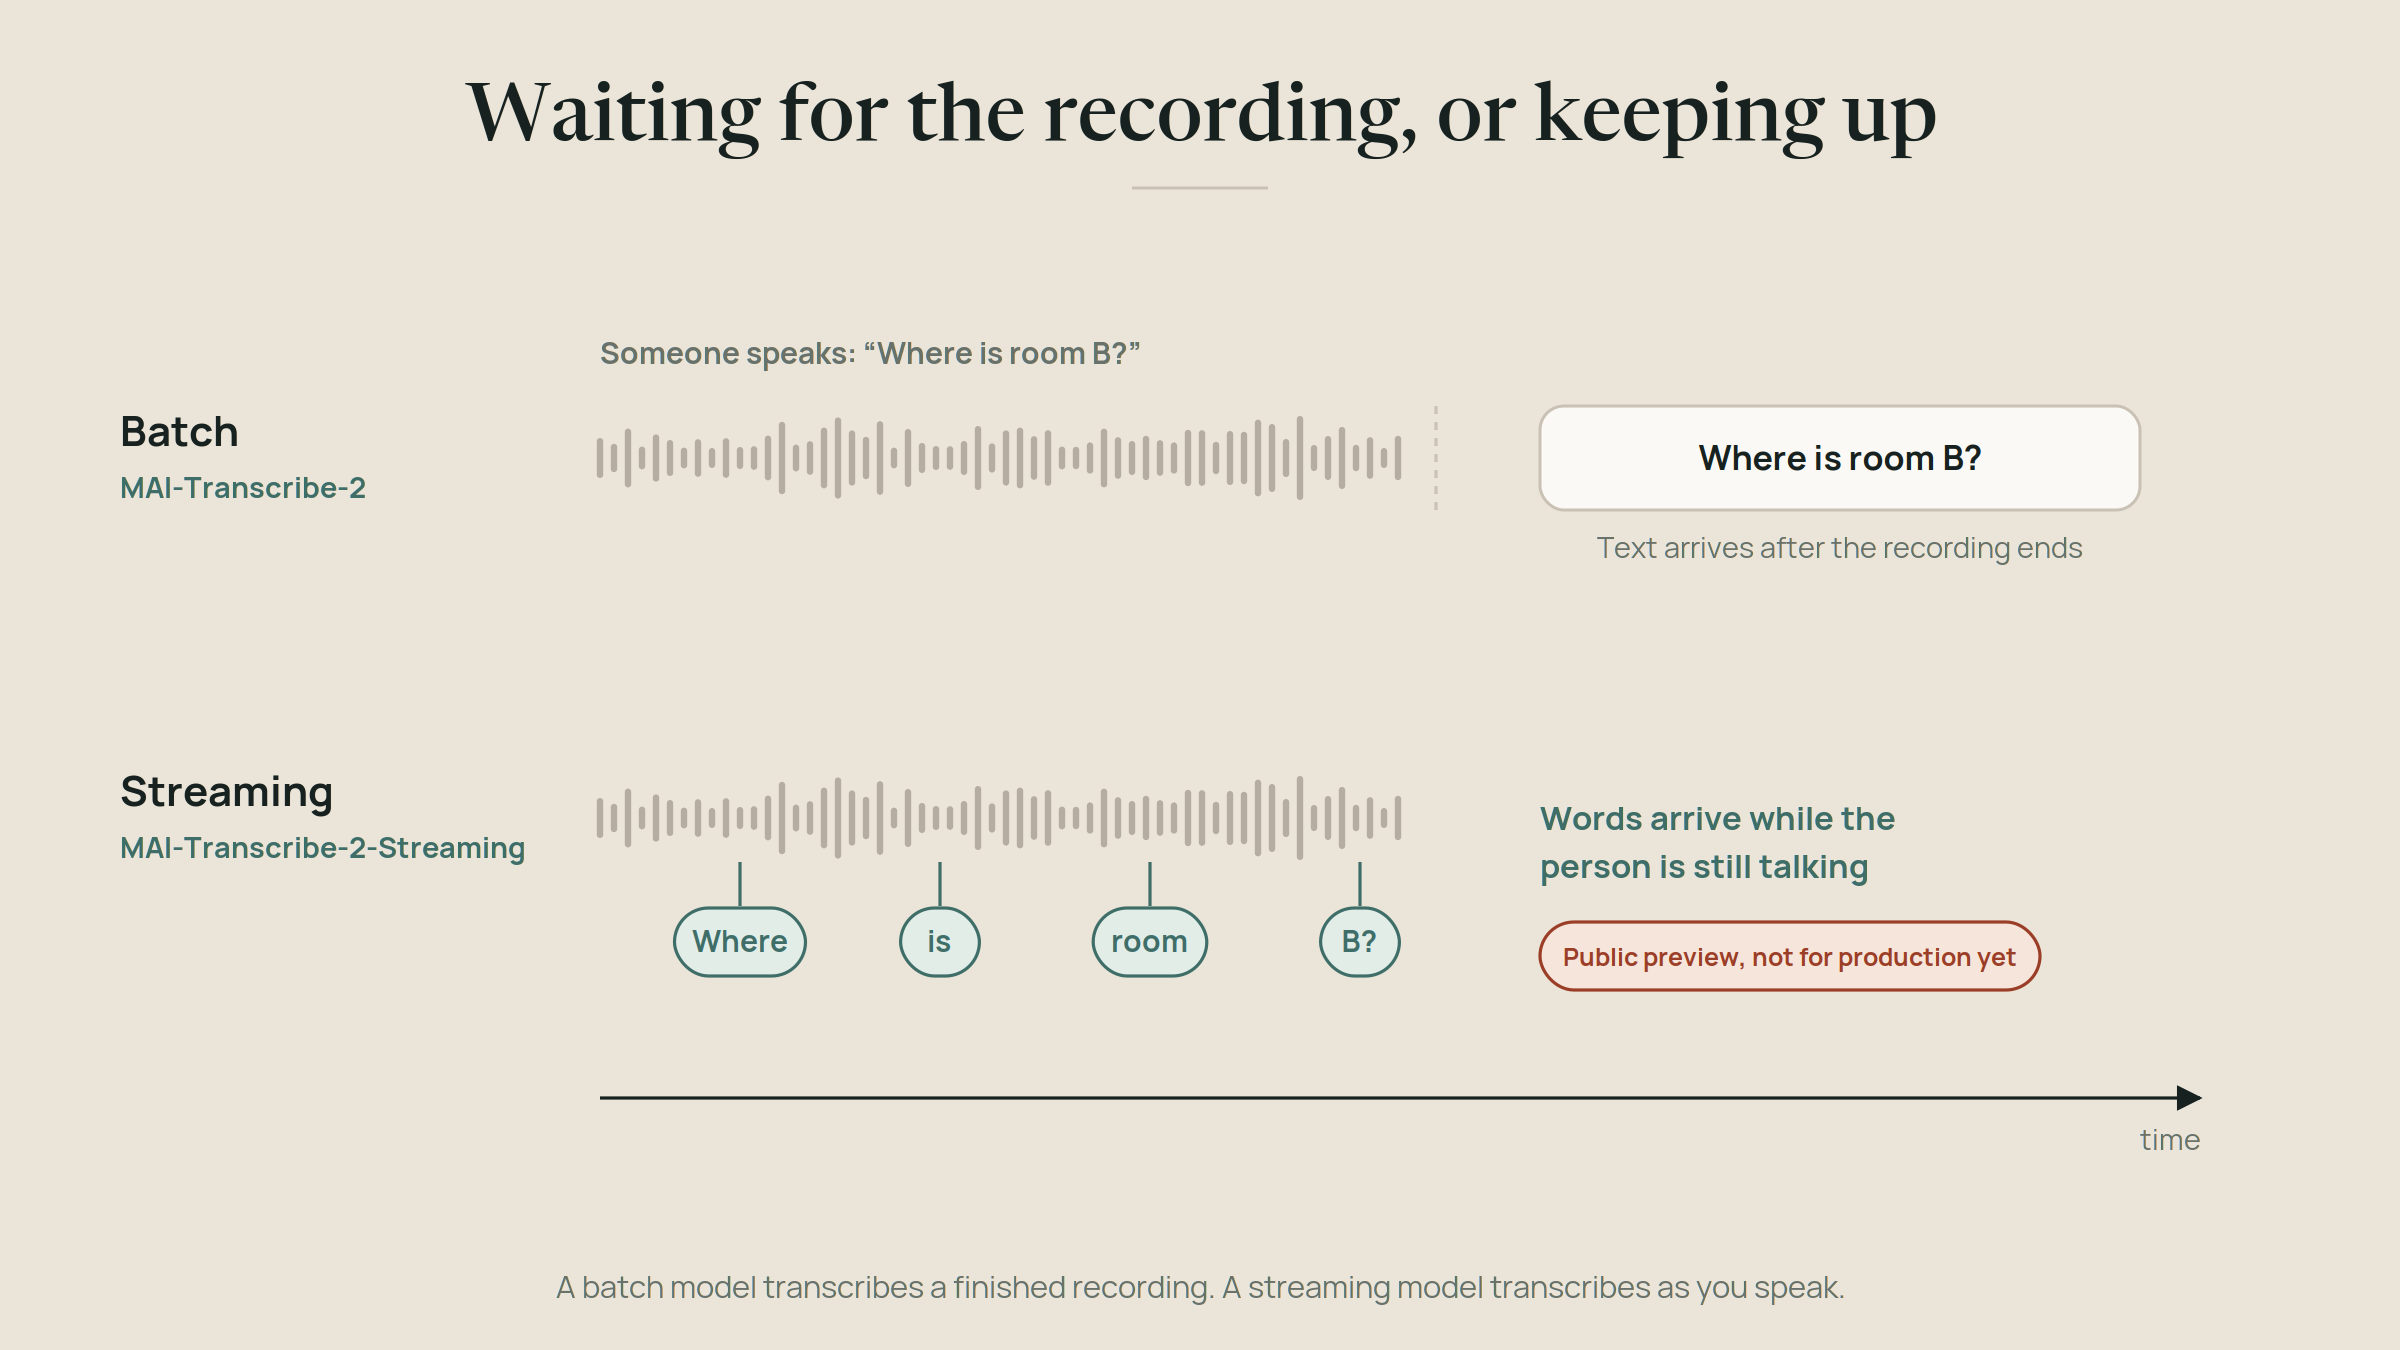
MAI-Transcribe-2-Streaming came out on October 1 and is Microsoft AI's first streaming model. The difference matters: a batch model waits for a finished recording, a streaming model transcribes while someone is still talking. It covers 60 languages and detects the language automatically, as you speak. Microsoft says it ranks first on Artificial Analysis for streaming transcription.
One caution worth knowing before you build: Microsoft's own documentation labels the streaming model a public preview, without a service-level agreement and not recommended for production yet. Great for prototypes. Wait before you put a call center on it.
Speak: MAI-Voice-2.1
Text-to-speech, or TTS, is the reverse: turning text into a spoken voice. Released on the same day as the streaming model, MAI-Voice-2.1 supports 23 languages and keeps one recognizable voice and a native-sounding accent across all of them. That solves a real problem: a bilingual assistant that changes personality every time it changes language.
There's also MAI-Voice-2.1-Flash, a cheaper and faster variant for high-volume, latency-sensitive work. Microsoft reports that in a test with 4,000 listeners, half rated the voices as equally or more human-like than real human recordings.
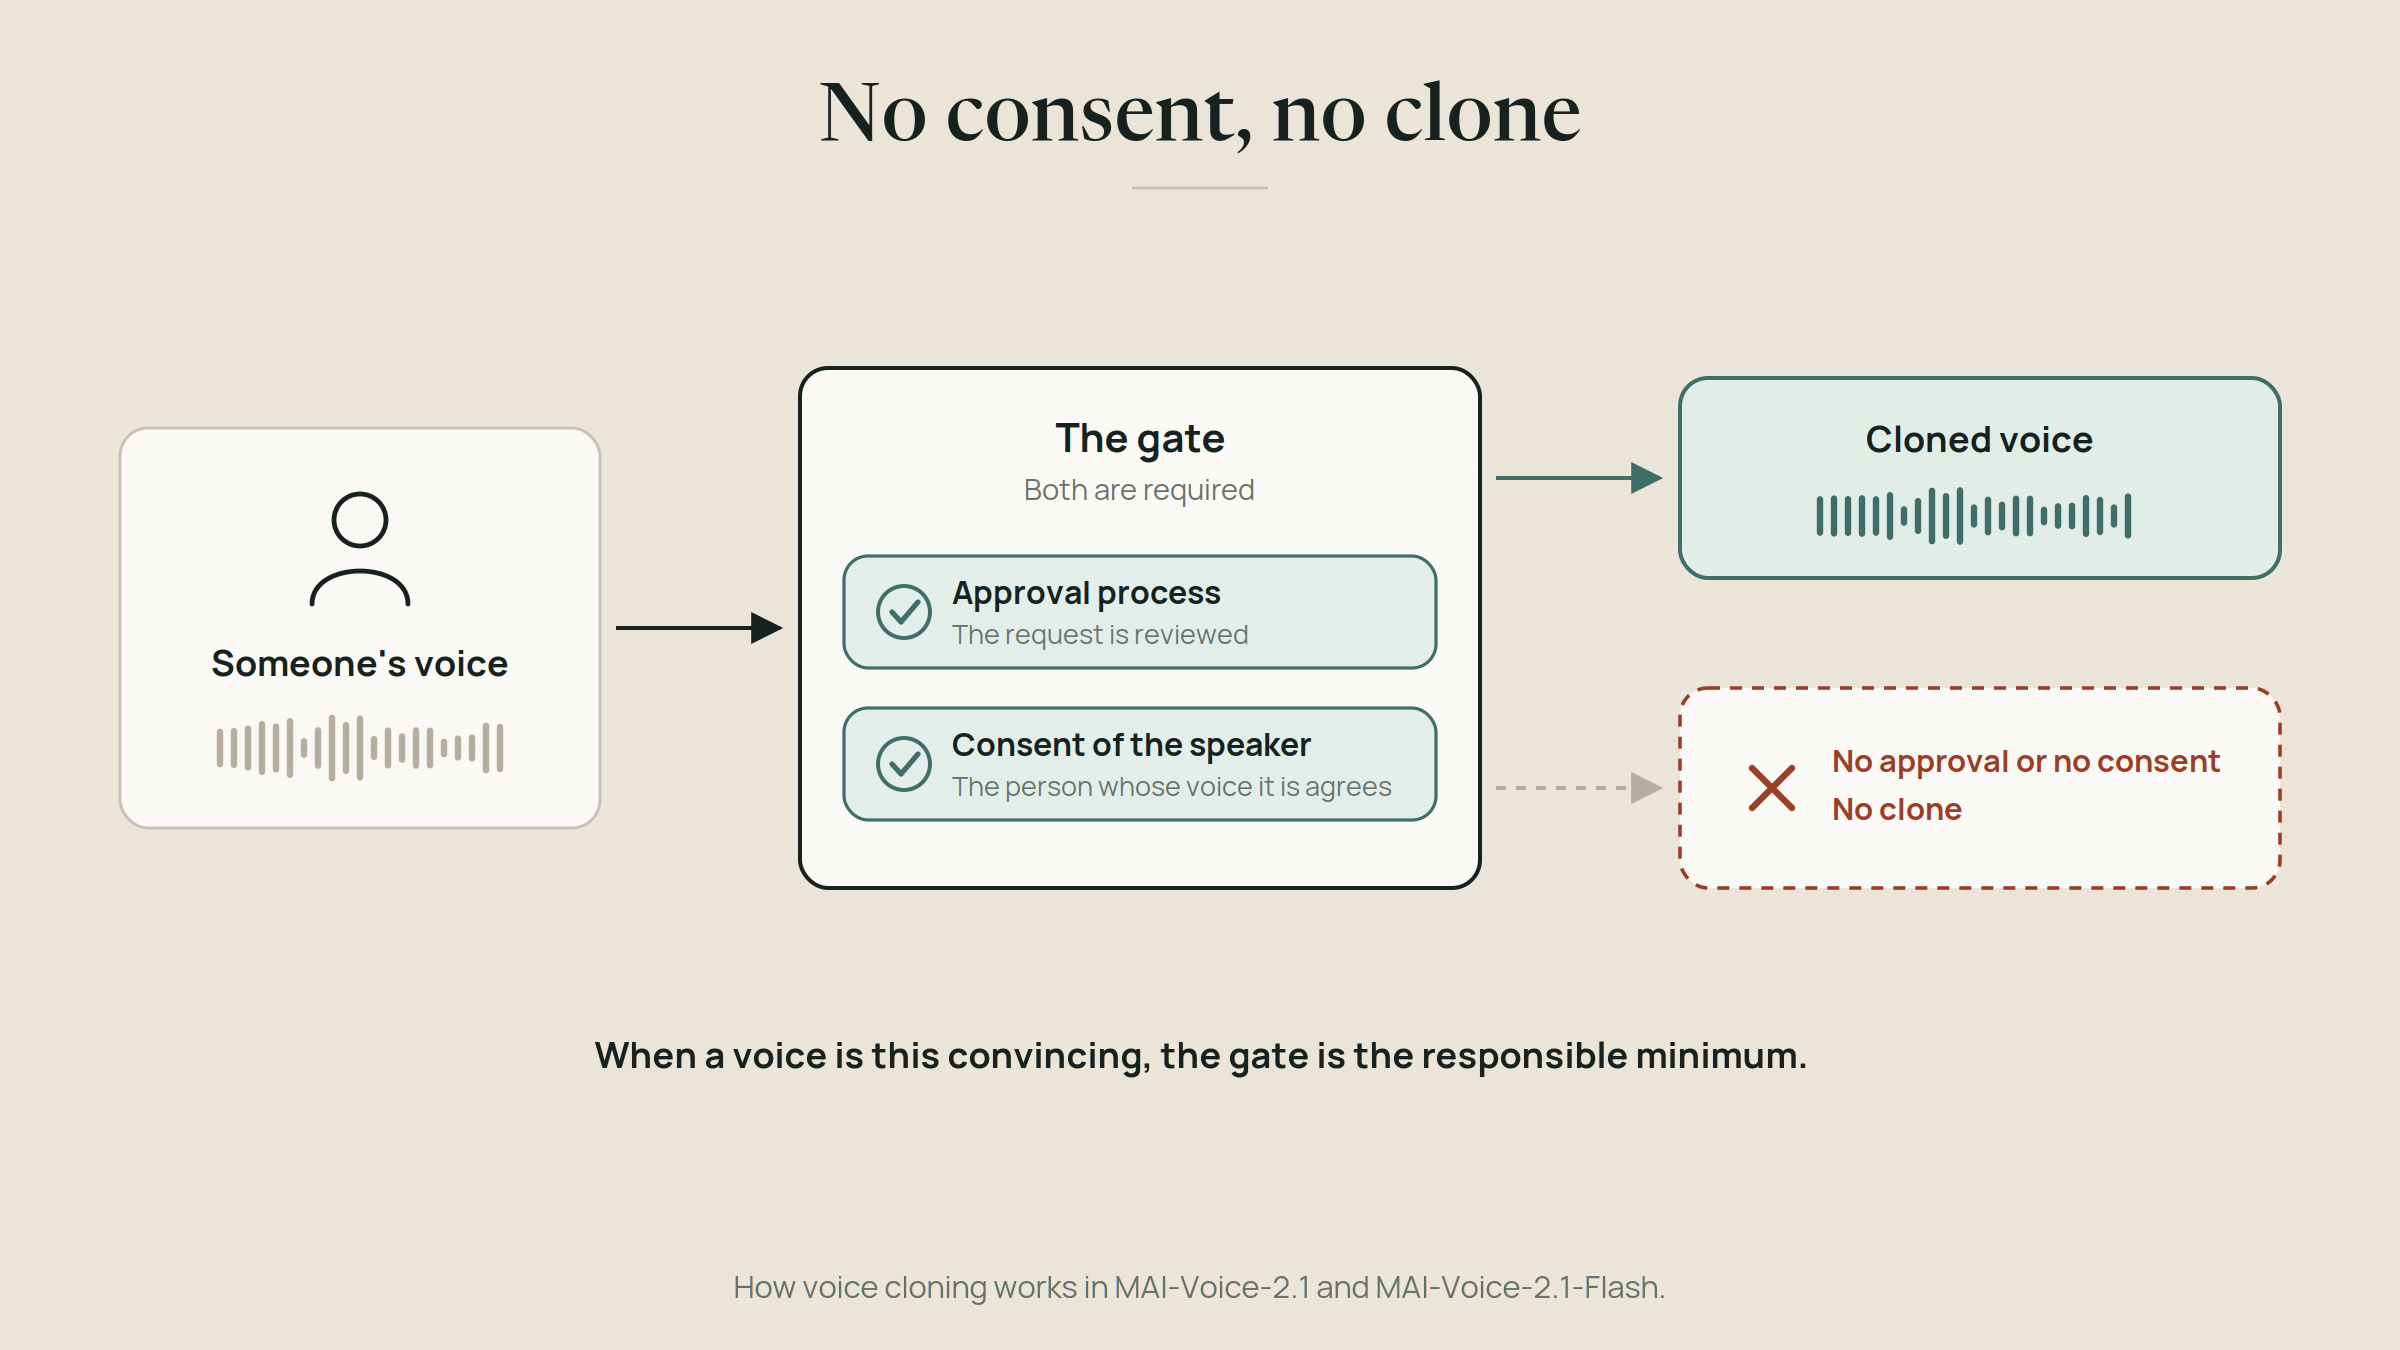
That last number is impressive and a little unsettling, which brings me to the part I find most important. Both voice models support voice cloning, but only through an approval process, and only with the consent of the person whose voice it is. When a voice is this convincing, that gate is not bureaucracy. It's the responsible minimum.
See: MAI-Image-2.6
MAI-Image-2.6 generates images from text, and edits existing images from a prompt. Microsoft announced it on August 10, when it debuted at number two on the Arena text-to-image leaderboard, behind OpenAI's GPT Image 2. It opened to the public in Microsoft Foundry in early September, together with a cheaper Flash version.
Its pitch isn't "best image model." It's quality per euro: Arena placed it on the price-performance frontier at roughly four cents per image, though your real cost depends on resolution and inputs. You may have used its predecessors without knowing it: earlier MAI image models power image features in PowerPoint and OneDrive.
DEMO (replace this block with the recording)
From question to floor sketch with MAI-Image-2.6

Goal
  Show that MAI-Image-2.6 can create an image from text and also edit
  an existing image, using the "Where is room B?" example from this series.

Where
  MAI Playground (no setup needed) or Microsoft Foundry.

Steps
  1. Select MAI-Image-2.6.
  2. Generate with this prompt:
     "A simple floor plan sketch of the second floor of a conference
     venue. Rooms labeled A, B and C, stairs, and toilets. Clean lines,
     light colors, white background, easy to read on a screen."
  3. Edit the result with this prompt:
     "Add a bold arrow from the stairs to the second door on the left,
     and label that room Room B."
  4. If the Flash version is available, run step 2 with it too and put
     both results side by side.

Capture
  A screen recording or GIF of steps 2 and 3, about 30 seconds, plus a
  still image of the side-by-side comparison.

Watch out for
  Image models can misspell text inside images. If a label comes out
  wrong, keep it in the demo and say so. It shows what to check before
  you put a generated image in front of users.
The real story: these models are building blocks
Look at the pattern across today's models. Fast, cheap, specialized. Each one does one thing very well. That's not a weakness, that's the design, and it's the same principle I use when I build agent systems: one model per role.
Microsoft says it directly about the voice pair: combining the streaming transcription model with MAI-Voice-2.1-Flash saves time on both ends of a voice conversation, the listening and the speaking, which leaves more time in the middle for an agent to actually think. In a voice agent, every few hundred milliseconds decides whether it feels like a conversation or like talking to a machine.
Which raises the obvious question: what's in the middle? That's where Day 2's thinker comes in, and it's what we'll put together on Day 5.
Try it yourself
All of these can be tried in the MAI Playground or Microsoft Foundry. The fun test for transcription: record yourself speaking two languages in one sentence, the way people actually talk, and see if it keeps up. For voice: give MAI-Voice-2.1 a paragraph that switches language halfway and listen to whether the voice stays the same person.
Tomorrow: the models come to the tools you already use.
Pass it on
Share this article
Read next