Five Days of Microsoft AI Models - Day 5
Putting It Together
A multilingual voice-agent design combining MAI and local models, plus four practical questions for choosing the right model for each role.
Four days, a lot of version numbers. Today the question that actually matters: how do you choose, and what do you build when you combine them?
My answer is the same one I give for every agent system I build: don't pick a model, hire a team. One model per role, each chosen for the job it does best.
A design: the voice agent
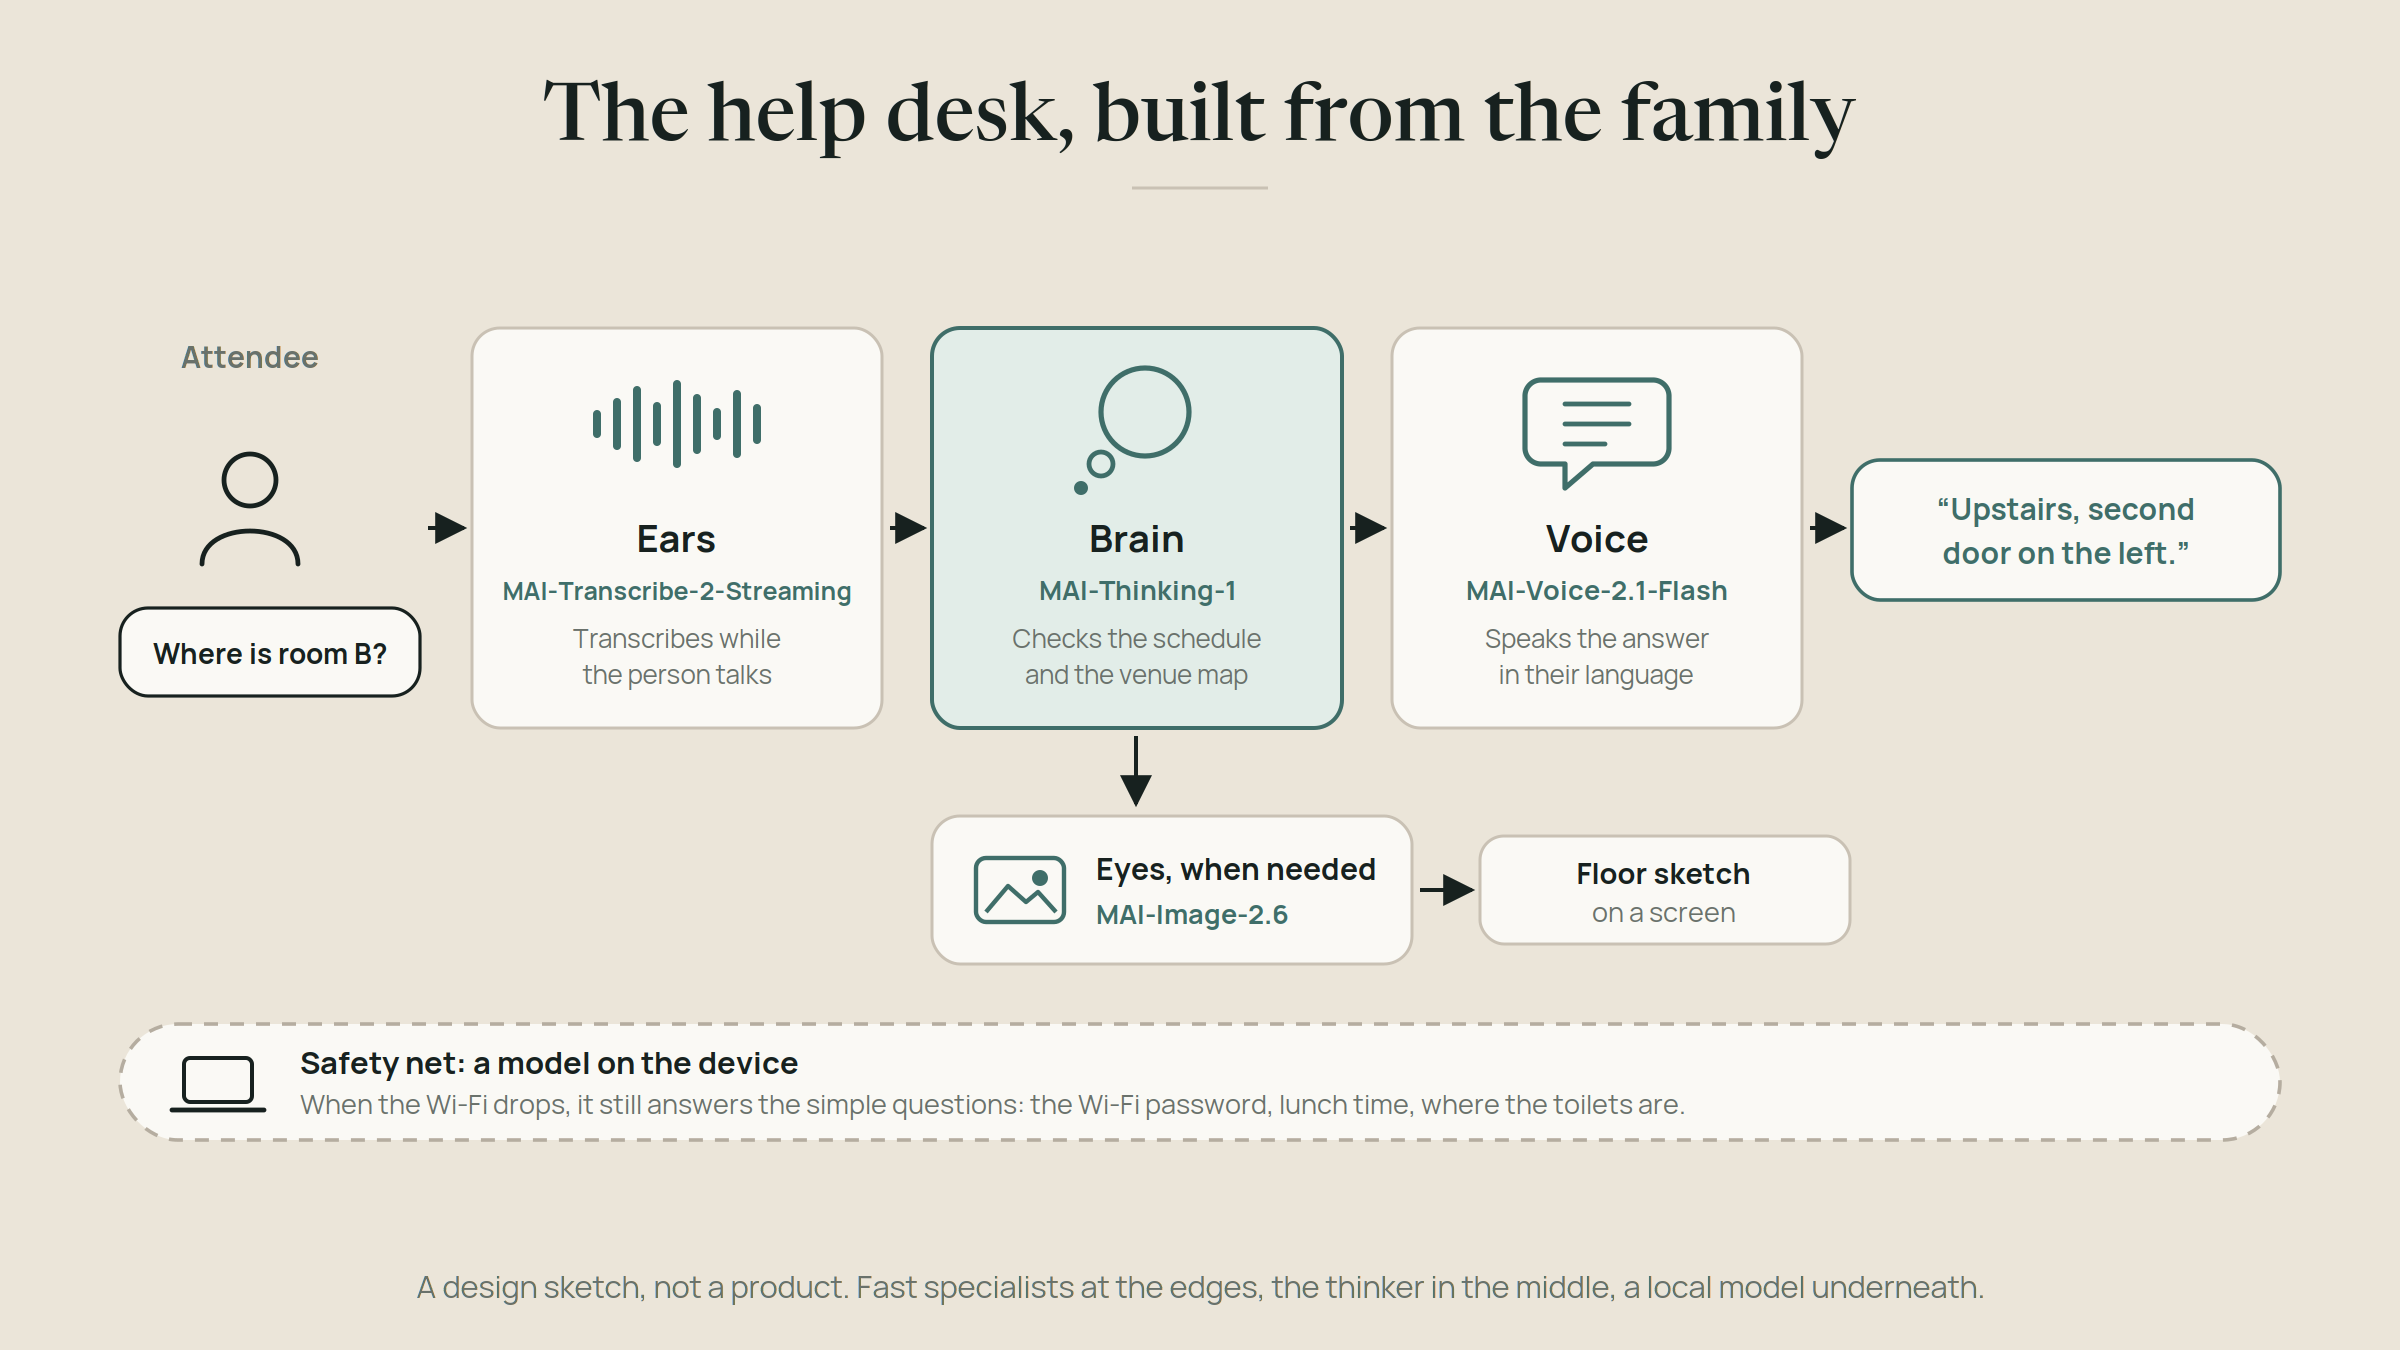
Let me show what that looks like with a design that uses almost everything from this week. Imagine a multilingual voice assistant for a community event, the kind of help desk I'd love at an AgentCon: an attendee walks up, asks a question in whatever language they speak, and gets a spoken answer.
Here's the team:
The ears: MAI-Transcribe-2-Streaming. It transcribes while the person is still talking and detects the language on its own. Every millisecond saved here is time the agent can use to think.
The brain: MAI-Thinking-1. It takes the transcribed question, works out what's being asked, calls tools for the schedule or the venue map, and decides on an answer. This is where reasoning earns its cost.
The voice: MAI-Voice-2.1-Flash. It speaks the answer quickly, in the attendee's language, with the same voice no matter which language that is.
The eyes, when needed: MAI-Image-2.6. "Where is room B?" is easier to answer with a quick generated floor sketch on a screen than with a paragraph.
The safety net: a local model. If the connection fails, as conference Wi-Fi tends to do, a model running on the device itself can still answer the simple, common questions: Wi-Fi password, lunch time, where the toilets are. Not brilliant, but always there. That's Day 4's hybrid idea doing its job.
Notice the shape. The fast, cheap specialists sit at the edges where speed matters. The expensive thinker sits in the middle where judgment matters. And the local model sits underneath as the thing that keeps working when the cloud is out of reach. That last role is the lesson from my open weights post, built into the design: never depend on something you can't leave, or in this case, something that can leave you.
How to choose: four questions
When I decide which model gets which role, I ask four questions.
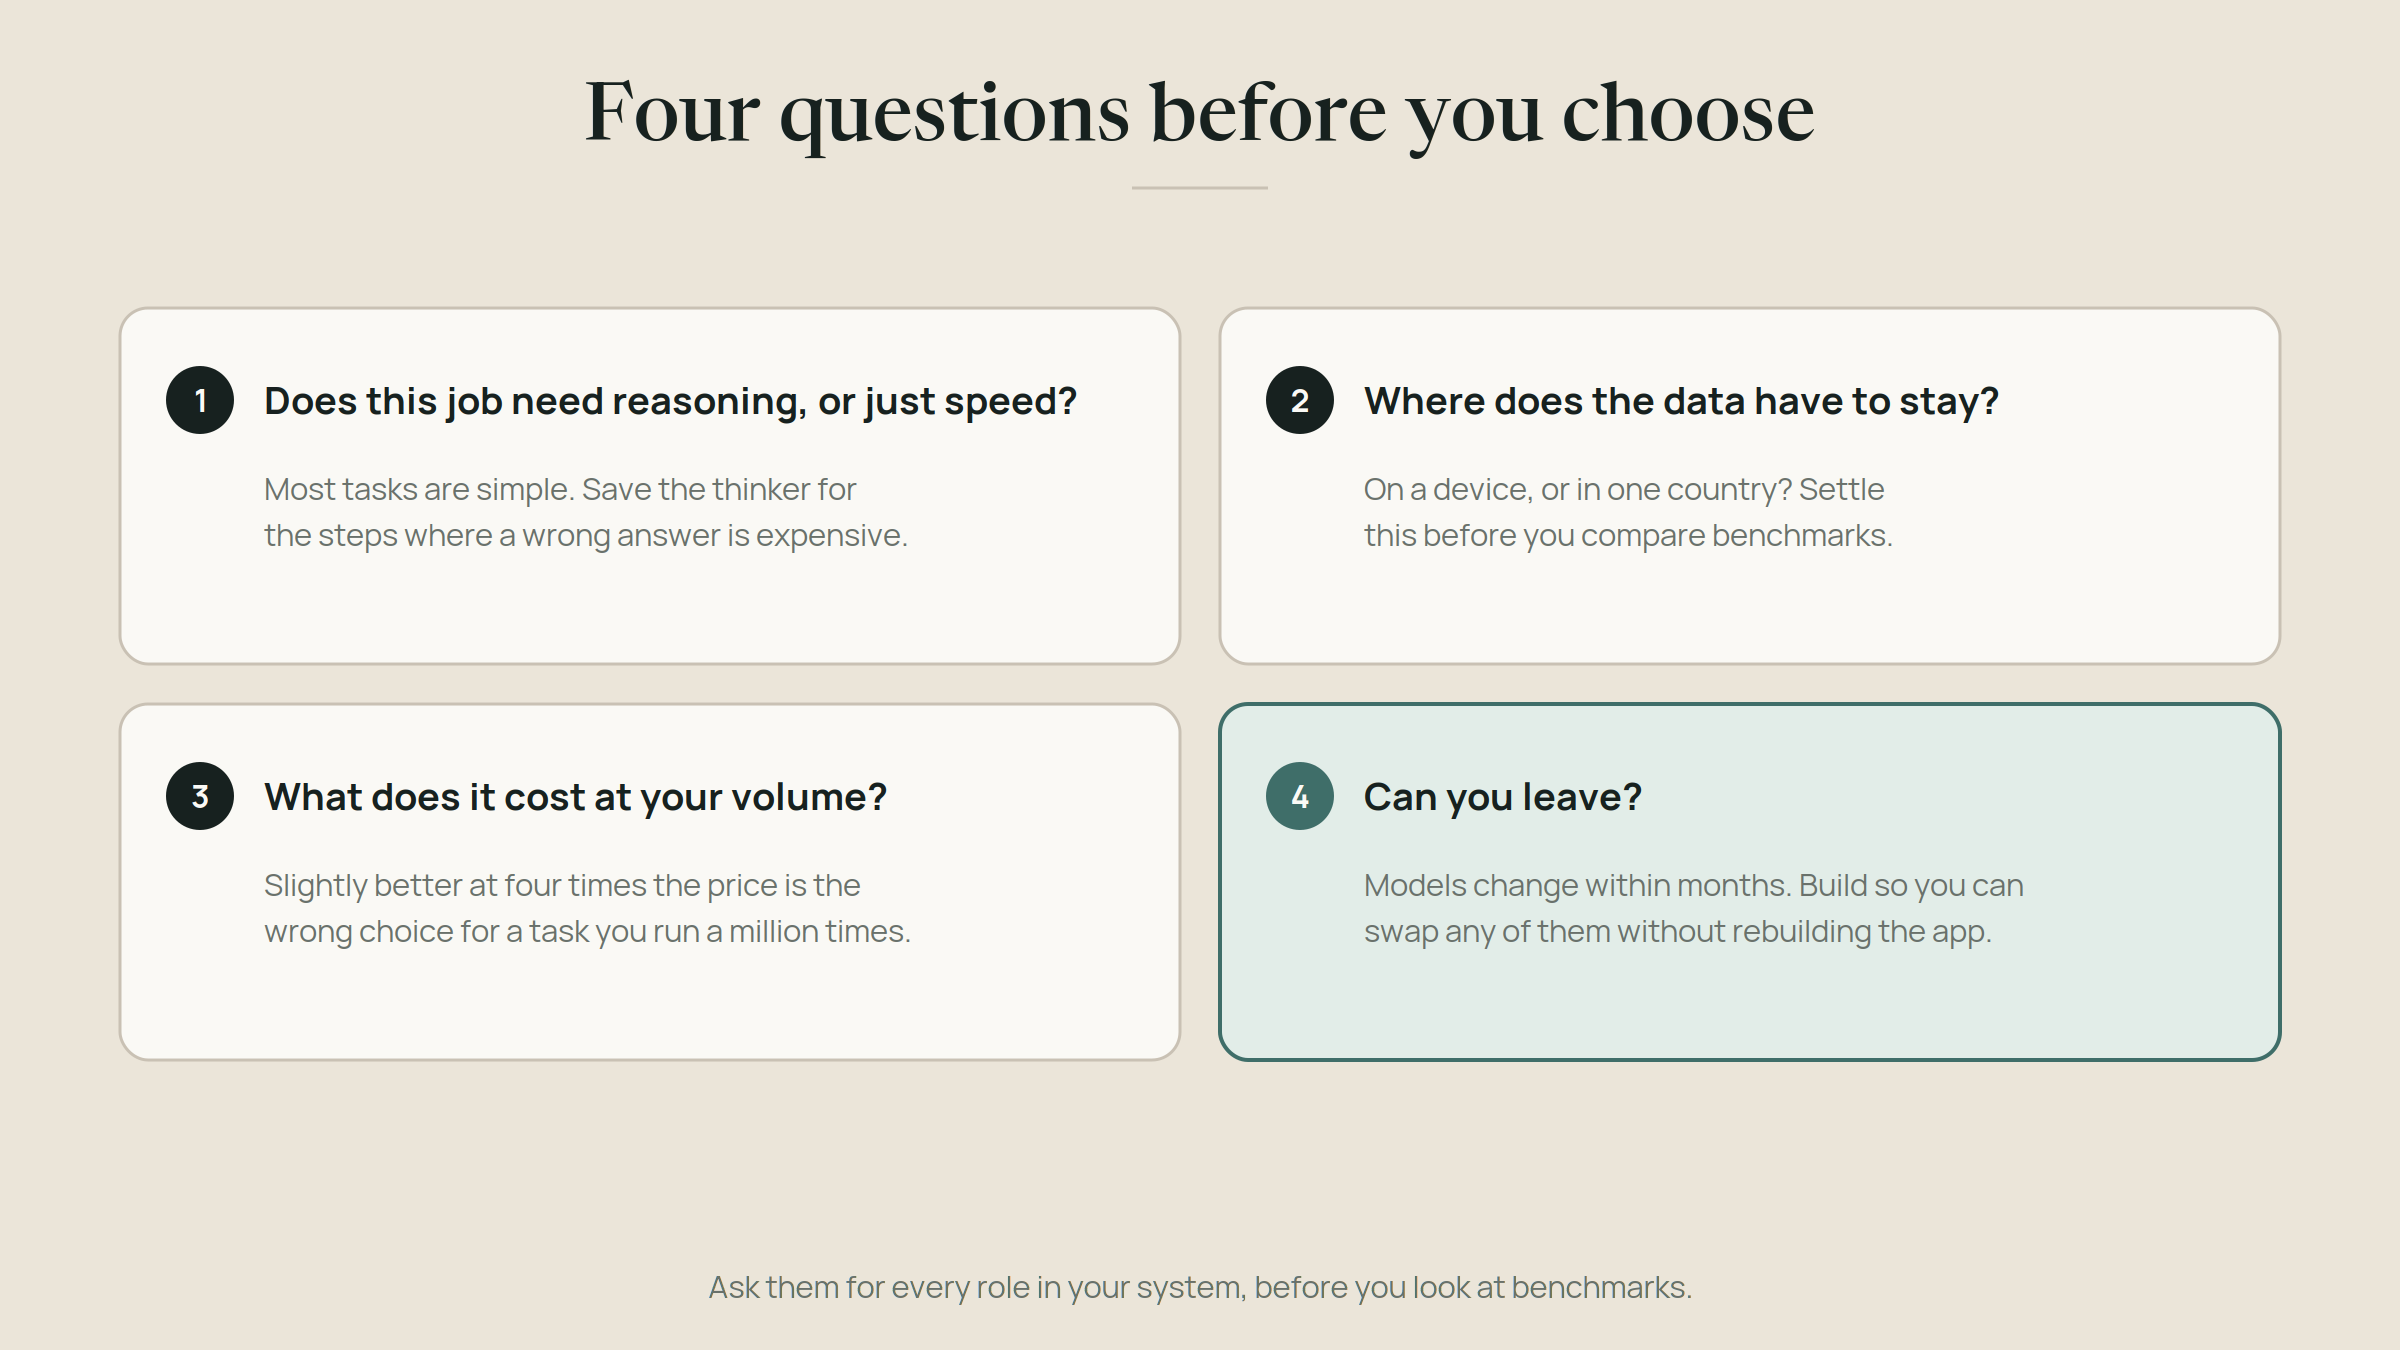
Does this job need reasoning, or just speed? Most tasks in an app are simple: classify, extract, transcribe, format. Give those to fast, specialized models. Save the reasoning model for the steps where a wrong answer is expensive.
Where does the data have to stay? If it can't leave a device or a country, that decides for you: a model on the device, or a cloud region that meets your requirements. Settle this before you compare benchmarks.
What does it cost at your volume? A model that's slightly better but costs four times as much is the wrong choice for a task you run a million times. Look at Day 3's prices per hour of audio and per image; at scale, those are the numbers that decide.
Can you leave? Every MAI model I covered this week launched or got a new version since June, and one was deprecated after three. That's progress, and it's also a warning. Build so you can swap any model in your team without rebuilding the app. A gateway helps here: when every model sits behind one API, trying a new one means changing a name, not rewriting code.
The swap, in code
Here's "Can you leave?" as code. The app never names a model. It asks for a role, and one small file decides which model and which door fill that role.
The file models.json:
{
  "voice": {
    "door": "openrouter",
    "model": "microsoft/mai-voice-2.1-flash",
    "voice": "en-US-Harper:MAI-Voice-2.1-Flash"
  },
  "narrator": {
    "door": "foundry",
    "voice": "en-US-Harper:MAI-Voice-2.1"
  }
}
The file team.mjs:
// The app asks for a role. models.json decides which model and door fill it.
// Usage: node team.mjs voice "Room B is upstairs, second door on the left."
import { readFile, writeFile } from "node:fs/promises";

const team = JSON.parse(await readFile(new URL("./models.json", import.meta.url), "utf8"));

// One small adapter per door. Adding a door means adding one function here.
const doors = {
  async foundry(text, role) {
    const lang = role.voice.split("-").slice(0, 2).join("-");
    const ssml = `<speak version="1.0" xml:lang="${lang}"><voice name="${role.voice}">${text}</voice></speak>`;
    const res = await fetch(
      `https://${process.env.SPEECH_REGION}.tts.speech.microsoft.com/cognitiveservices/v1`,
      {
        method: "POST",
        headers: {
          "Ocp-Apim-Subscription-Key": process.env.SPEECH_KEY,
          "Content-Type": "application/ssml+xml",
          "X-Microsoft-OutputFormat": "audio-24khz-48kbitrate-mono-mp3",
        },
        body: ssml,
      }
    );
    if (!res.ok) throw new Error(`foundry: ${res.status} ${await res.text()}`);
    return new Uint8Array(await res.arrayBuffer());
  },

  async openrouter(text, role) {
    const res = await fetch("https://openrouter.ai/api/v1/audio/speech", {
      method: "POST",
      headers: {
        Authorization: `Bearer ${process.env.OPENROUTER_API_KEY}`,
        "Content-Type": "application/json",
      },
      body: JSON.stringify({ model: role.model, input: text, voice: role.voice, response_format: "mp3" }),
    });
    if (!res.ok) throw new Error(`openrouter: ${res.status} ${await res.text()}`);
    return new Uint8Array(await res.arrayBuffer());
  },
};

export async function say(roleName, text) {
  const role = team[roleName];
  if (!role) throw new Error(`No model configured for the role "${roleName}"`);
  return doors[role.door](text, role);
}

if (process.argv[2]) {
  const [roleName, text] = process.argv.slice(2);
  const audio = await say(roleName, text);
  const file = `${roleName}-${team[roleName].door}.mp3`;
  await writeFile(file, audio);
  console.log(`${roleName} via ${team[roleName].door}: saved ${file}`);
}
Run node team.mjs voice "Room B is upstairs, second door on the left." and the answer comes through OpenRouter. Change "openrouter" to "foundry" in models.json, run the same command, and the same request goes through Foundry. No code changes, one line in one file.
I kept the sample to the voice roles, because MAI-Voice-2.1-Flash is available at every door. The ears and the brain work the same way: one entry in models.json per role, and one small adapter per door. Day 4 includes a Vercel code example as another possible adapter, not a recorded demo.
Try the building blocks
You don't have to build the whole help desk to explore the parts. My MAI demos repository has independent notebooks following A Bit of AI: give a podcast a voice, then turn a recorded conversation into useful text.
These are building blocks, not a complete implementation of the help-desk agent above. They use Azure Speech directly, not Vercel, and the walkthroughs do not demonstrate the OpenRouter-to-Foundry swap.
Give the podcast a voice
The MAI-Voice-2.1 and Flash notebook starts with a podcast welcome. Try different delivery styles, hear English and Dutch, and compare the full model with Flash using the same excerpt. That last comparison is the practical version of choosing the right model for a role.
Watch the voice walkthrough (7 minutes 14 seconds), then open the voice notebook and follow its setup instructions.
Start with the prebuilt voices, which are synthetic stand-ins rather than the hosts' actual voices. The core examples need no recordings or voice-cloning approval. The optional personal-voice example has separate approval, permission, and recorded-consent requirements.
Turn a recording into a working transcript
The MAI-Transcribe-2 notebook takes a recorded conversation through an editor's workflow: verbatim transcription, anonymous speaker labels, word timestamps, clean versus verbatim output, and keyword hints. It also includes a Dutch welcome to explore automatic language detection, not translation.
Watch the transcription walkthrough (6 minutes), then open the transcription notebook and follow its setup instructions.
This is file transcription, not the streaming ears in the help-desk design. Bring a recording you have permission to use; no audio is bundled. Review the transcript before sharing it.
An experimental next step: live captions
The separate MAI-Transcribe-2-Streaming notebook explores provisional captions while someone speaks and finalized text afterwards. It's closer to the help desk's listening role, but the browser-microphone-to-Azure flow still needs end-to-end verification in the target environment. Treat it as an experimental example, not a verified live demo. Follow its own streaming setup instructions; it needs a streaming deployment and microphone permissions.
The repository includes a shared Codespaces and dev-container setup. Creating the environment does not run the models: synthesis and transcription calls incur Azure charges when you run them, and Codespaces compute is billed separately. Keep credentials and private recordings out of commits.
And the non-Microsoft models?
A fair question to end on, especially from someone who works at Microsoft. The answer: Microsoft Foundry also offers models from OpenAI, Anthropic, Meta, Mistral and many others, and in my own projects I pick whichever model is best for each role, whoever made it.
What this week showed me is that Microsoft's own models have become real candidates for many of those roles, especially speech, images and fast coding, where they compete strongly on quality per euro. That's a different situation from a year ago, when the answer for most roles was simply "someone else's model."
What I take from this week
Microsoft now has answers to two different questions. MAI says: we can build competitive models ourselves, quickly, and specialized for real jobs. Windows says: and they can run where you are.
The smartest systems will use both. A cloud team for the hard and heavy work, local models for privacy, speed and reach, and an architecture that lets you change your mind next quarter, because next quarter there will be new versions again.
Thanks for following along this week. If you build something with these models, I'd love to see it. Show me the demo, and especially show me the part that broke.
Download team.mjs and models.json into the same folder to try the role-based example.
Pass it on
Share this article
Read next